How to Scrape a Website: Ultimate Guide for 2026
A practical guide to choosing an authorized data source, collecting only what you need, validating results, and handling legal and technical limits.
Step-by-step guides to capturing the web: screenshots, full pages, elements, devices and more.
A practical guide to choosing an authorized data source, collecting only what you need, validating results, and handling legal and technical limits.
Learn when SQL triggers are useful, how timing and row scope work, and how to write safer triggers across PostgreSQL, SQLite, MySQL, and SQL Server.
Website terms can restrict scraping when a contract was formed, but public access, login status, notice, and technical barriers all affect the analysis.
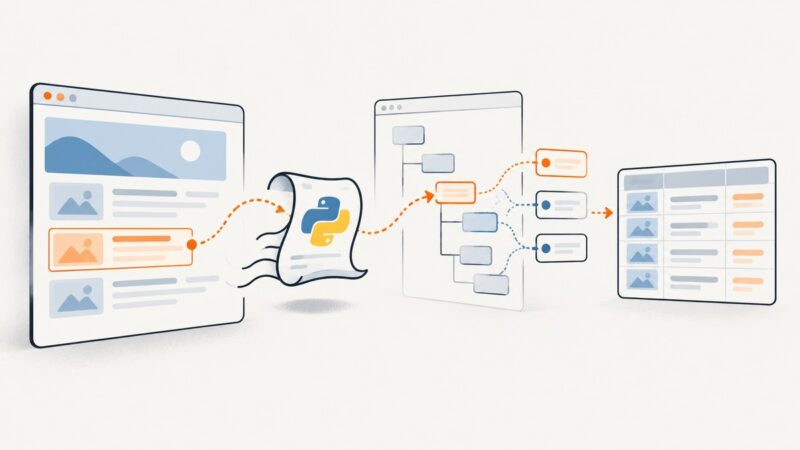
Learn how to scrape responsibly: permission, robots.txt, privacy, low-impact crawling, secure data handling, and practical Python code.
Build a reproducible Paris bakery dataset, check which shops are open, and optimize a morning ride against distance, time and cycling comfort.
Reduce repetitive monitoring alerts without losing outage visibility. Tune detection, deduplicate incidents, silence maintenance, and verify the signal.
SOCKS5 relays application traffic through a proxy server. Learn how its handshake, commands, DNS behavior and security limits affect when to use it.
Practical Python recipes for static and JavaScript sites, with parsing, retries, robots.txt, rate control, troubleshooting, and production guidance.
Design scraper inputs as a clear contract: choose useful fields, defaults, validation rules, and UI controls, with runnable Apify and Python examples.
Learn lxml in Python: parse XML and HTML, query with XPath, handle namespaces, validate documents, and avoid common parser errors.
Blurry, stretched, or oversized screenshots usually come from mixing CSS pixels, device pixels, viewport scale, and aspect ratios. Learn how to diagnose and fix each cause.
Learn how to sample localized search results with proxies, keep comparisons consistent, and interpret rank changes without treating one result as universal.
An API is a set of rules that lets software use another program’s data or capabilities. Learn how API calls work, how common API types differ, and how to make a web API request.
Choose an extraction model and turn reliability, data quality, freshness, delivery, and support expectations into measurable contract terms.
Learn which browser automation layer fits your custom action, with runnable Selenium examples and guidance for IDE, browser, Playwright, and WebDriver extensions.
Compare managed APIs, Scrapy, and Apify for retail data collection. Learn how to choose, build a pipeline, handle failures, and control costs.
A JSON parser turns JSON text into values your program can use. Learn the syntax, runnable JavaScript and Python examples, errors, safety, and limits.
Learn a reliable Python scraping workflow: fetch HTML, select data, handle pagination, choose tools, and save clean structured results.