How to Bulk Create From Canva Templates
Use Canva Bulk Create to turn CSV, XLSX, or Canva Sheets rows into personalized designs, with mapping, previews, limits, troubleshooting, and automation options.
Use Canva Bulk Create to turn CSV, XLSX, or Canva Sheets rows into personalized designs, with mapping, previews, limits, troubleshooting, and automation options.
Make an HTML table fill its container, keep columns readable, and handle responsive layouts with practical CSS, debugging steps, and examples.
A squashed full-page screenshot usually means you captured the wrong scroll area or changed pixel scale. Diagnose both with these fixes and runnable examples.
Use customElements.whenDefined(), component-ready signals, and bounded waits to capture fully rendered web components with Playwright or Puppeteer.
Google Maps Platform terms restrict scraping or exporting Maps content. Learn when to use Places API, what you may store and display, and how to choose a compliant data source.
Capture an entire scrollable webpage in Java with Playwright, or use Selenium and Chrome DevTools when your existing stack calls for it.
Build a practical brand system with approved assets, constrained templates, review rules, and a workflow your marketing team can run without a designer on every request.
Wait for the page state your screenshot needs, not just navigation. Learn reliable Capybara and Selenium patterns for custom elements in Ruby.
Learn how to fetch HTML, select the right table, normalize rows, preserve links, handle irregular markup, and export clean data with BeautifulSoup or pandas.
Wait for a custom element to register, then verify its real render-ready signal before capturing a page with Playwright or Puppeteer.
Learn how to identify a website’s rendered colors and fonts with Chrome DevTools, CSS Overview, and repeatable browser automation.
Use Wappalyzer or BuiltWith for a quick scan, then verify the clues in page source, scripts, cookies, and response headers.
Build a respectful Cadena SER sports scraper with RSS-first discovery, robots.txt checks, resilient parsing, deduplication, and compliance safeguards.
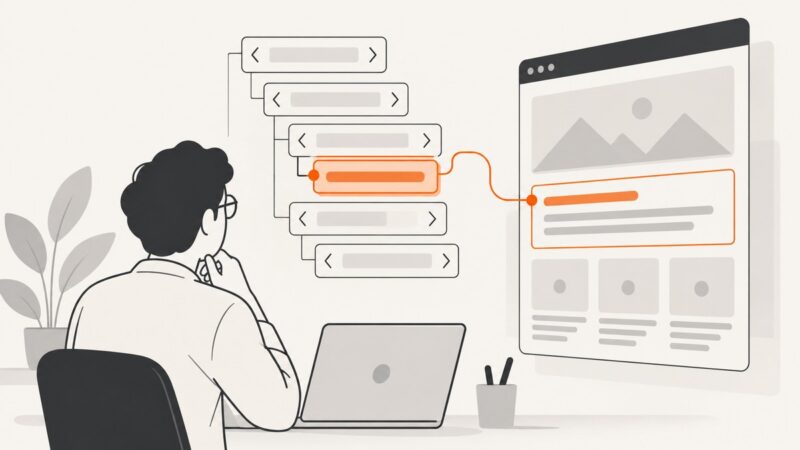
Find exact or partial text in HTML with BeautifulSoup’s `string=` filters, return matching tags, and handle nested markup, whitespace, and common errors.
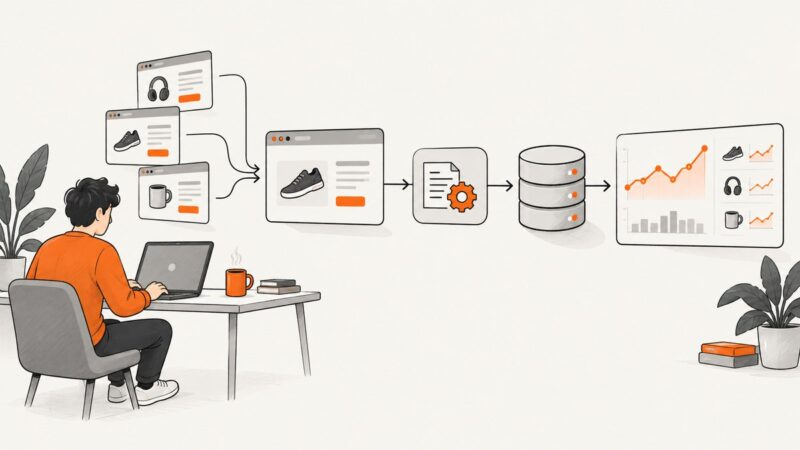
Build a reliable, permitted web data pipeline in Zapier using RSS, APIs, webhooks, schedules, Web Reader, and Web Search.
Hide cookie banners cleanly in screenshots with Playwright selectors, iframe-aware consent handling, validation steps, and a simpler API option.
Create a thumbnail for Bluesky link previews, add the Open Graph metadata your page needs, and understand how clients build website cards.
Capture AJAX, XHR, and fetch traffic in Selenium with Chrome CDP, WebDriver BiDi, or Selenium Wire. Learn how to match requests, read response bodies, and debug missed events.