Mastering Python cURL Requests: A Practical Guide for Developers
Translate cURL commands into reliable Python Requests code with timeouts, auth, sessions, uploads, retries, curl_cffi, and troubleshooting.
Step-by-step guides to capturing the web: screenshots, full pages, elements, devices and more.
Translate cURL commands into reliable Python Requests code with timeouts, auth, sessions, uploads, retries, curl_cffi, and troubleshooting.
Reuse Playwright storageState safely with page objects, setup projects, fixtures, worker isolation, API login, and troubleshooting.
Learn how screenshot APIs render URLs into images, choose a service, and build reliable captures with cURL, Python, or Node.js.
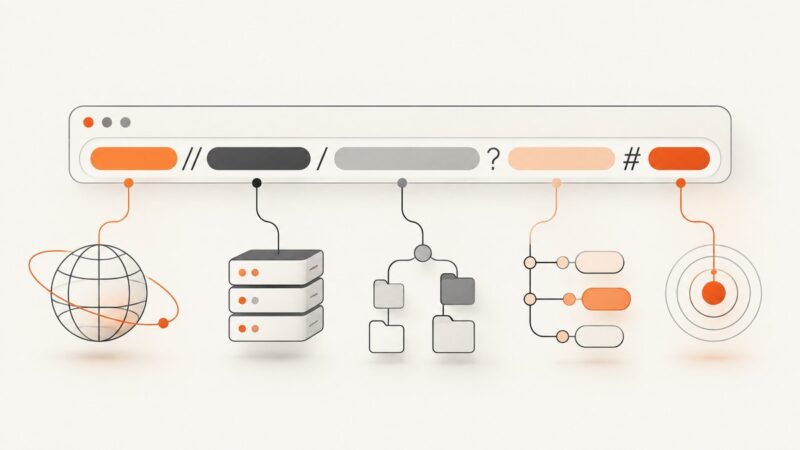
Learn what a URL is, how every part works, how browsers use it, and how to spot unsafe or misleading web addresses.
Signed URLs grant time-limited access to a specific resource without sharing an account credential. Learn how signatures, expiration, provider differences, and security tradeoffs work.
Learn what web scraping is, how scrapers collect structured data, when to use an API, and how to build a reliable, responsible workflow.
Build a reliable visual history of website changes with scheduled screenshots, stable capture settings, noise controls, and reviewable diffs.
Learn how session recordings reconstruct real user journeys, what they reveal, how to protect private data, and how to choose a replay tool.
Learn how to lower Webshare proxy costs by matching proxy type, bandwidth, and commitment to your workload—and when to change plans.
Walmart’s terms require express prior written consent to scrape or gather site materials. Learn how to confirm authorized access and plan a responsible data project.
A query string is the part of a URL after `?`. Learn how parameters work, how they differ from paths and fragments, and how to read and encode them in JavaScript.
Choose a screenshot workflow by capture type, privacy, editing needs, compatibility, and free limits. Compare browser tools with hosted URL capture.
Choose the right way to turn a web page or HTML into a PDF, editable Word document, or MP4, with practical workflows and runnable examples.
Private proxies route scraper traffic through a dedicated IP. Learn how they work, what to compare, and how to use them responsibly.
Capture website screenshots in TypeScript with raw HTTP, SDKs, error handling, options, and a production-ready ScreenshotNeo alternative.
An SDK is a software development kit: APIs, libraries, tools, documentation and examples that help you build for a platform or service.
A screenshot’s filename, file metadata and cloud display can show different times. Find the layer that changed and troubleshoot it without guessing.
Puppeteer automates browser work from JavaScript: interaction, testing, screenshots, PDFs, performance traces and more. Learn when it helps, how to start, and when you can skip browser setup.