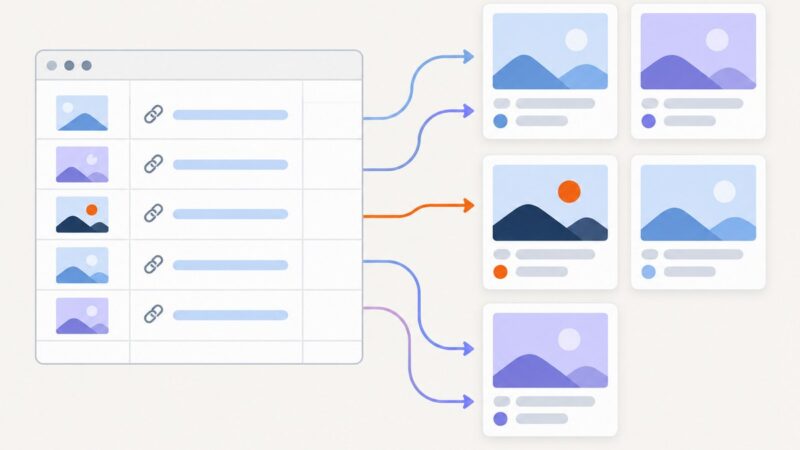
Bulk Image Generation for a Webflow CMS Collection
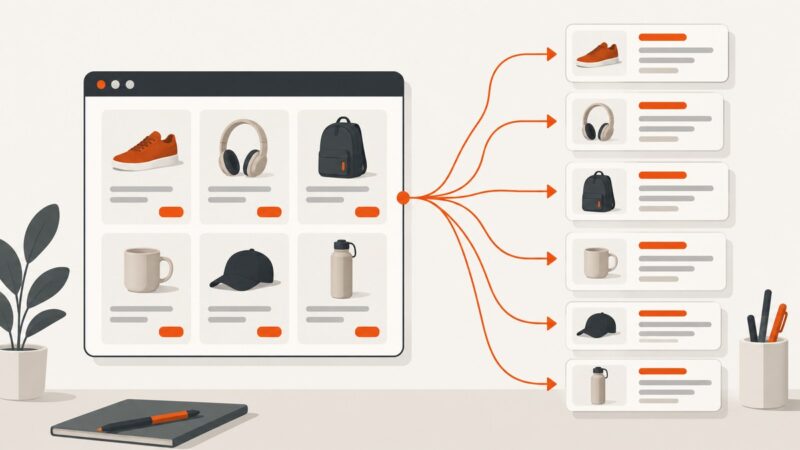
Generate or source images in batches, then populate Webflow CMS image fields reliably with CSV imports or the CMS API.
Generate or source images in batches, then populate Webflow CMS image fields reliably with CSV imports or the CMS API.
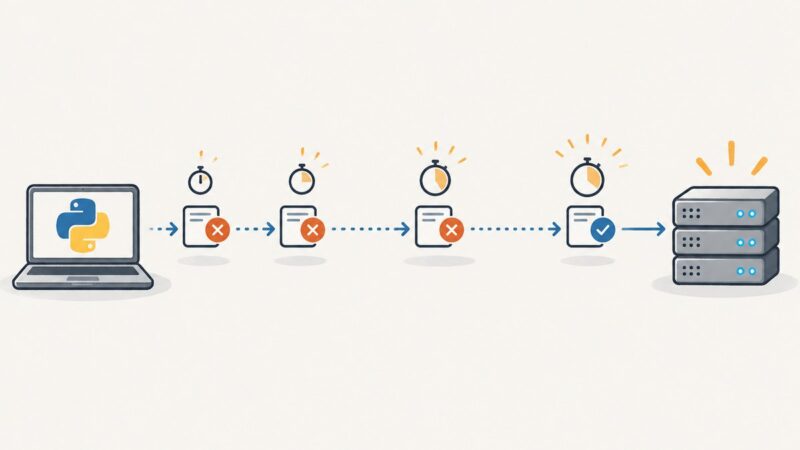
Add bounded retries to Python requests with urllib3 Retry, exponential backoff, jitter, timeouts, and safe handling for HTTP 429 and 5xx responses.
Learn a reliable PHP scraping pipeline: fetch HTML, parse it with DOMXPath or DomCrawler, handle failures, and know when JavaScript needs a browser.
Use ChatGPT to design a scraper, run network code safely outside Data Analysis, validate results, and automate clean screenshots when needed.
Configure Chrome downloads, wait for completion, verify files, and troubleshoot PDFs, authentication, timeouts, and browser-version differences in Puppeteer.
Change DNS servers safely on Windows, macOS, and Linux, benchmark locally, use encrypted DNS, and know when a resolver change will not help.
Learn how hosted browser services work—and why Zomato scraping requires written authorization or an approved API relationship first.
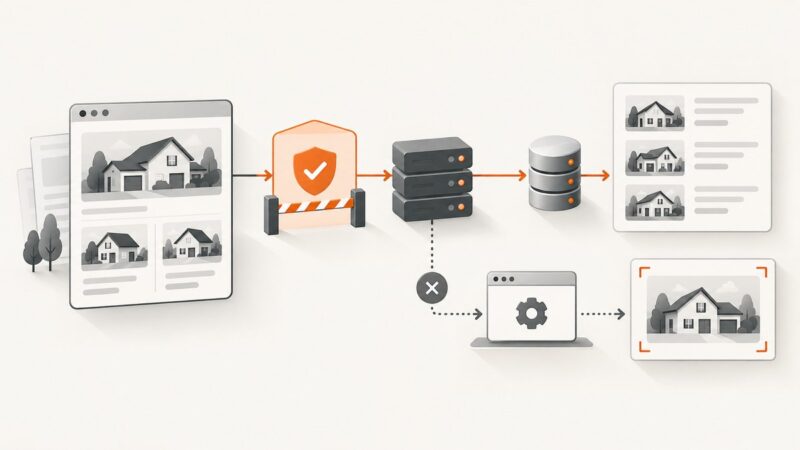
Build a real estate data pipeline around permission, licensed sources, reliable extraction, and careful validation. Includes a runnable Python example for authorized HTML.
Inject JavaScript before or after a page loads, wait for async content, then capture a reliable screenshot or PDF with Playwright, Puppeteer, or a hosted API.
Learn BeautifulSoup find_all class, find, and CSS selectors with runnable Python examples, edge cases, debugging tips, and production guidance.
Wait for the element or page state that makes a screenshot useful—not just for navigation to finish. Runnable Puppeteer, Playwright, Selenium, cURL, Python, and Node.js examples included.
Learn the permission-first way to collect Facebook data, handle rate limits, and avoid violations instead of chasing unreliable evasion tricks.
Learn a reliable Beautiful Soup workflow: fetch HTML, choose a parser, extract data, handle failures, and capture JavaScript pages when needed.
For video details, Bilibili’s documented route is its authorized Open Platform API—not an unrestricted public-page scraper. Learn the access requirements, signing workflow, runnable examples, and safe alternatives.
Realtor.com prohibits scraping without written permission. Learn the compliant API path, technical workflow, failure handling, and screenshot options.
Extract webpage data with plain-language instructions, then make results dependable with schemas, validation, and provenance. Includes runnable code and workflow guidance.
Use Playwright routes to block images, fonts, scripts, or other requests in Python. Choose page or context scope and handle service workers and caching deliberately.
BBC Sport discourages scraping. Learn the permitted alternatives: RSS, permission-based access, and safe page capture for authorized use.