Convert Raw HTML to PDF in PHP with Guzzle
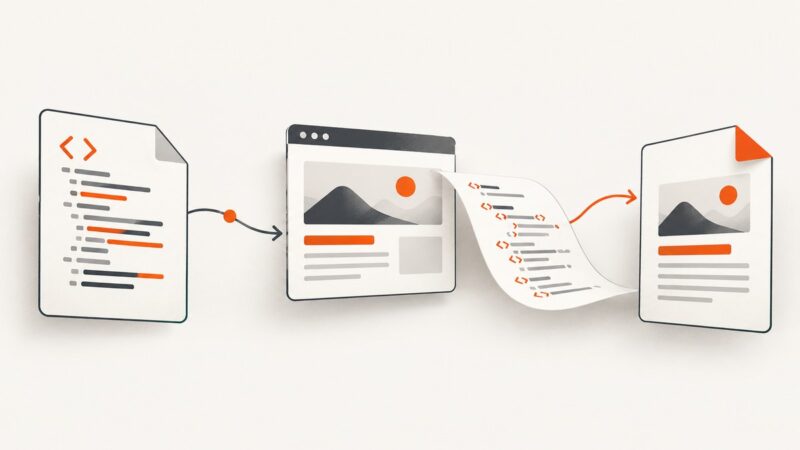
Use Guzzle to fetch HTML and Dompdf to render it as a PDF. Learn the complete workflow, renderer choices, security controls, and common fixes.
Use Guzzle to fetch HTML and Dompdf to render it as a PDF. Learn the complete workflow, renderer choices, security controls, and common fixes.
Use Playwright to scrape JavaScript-rendered pages with stable locators, explicit waits, pagination, and clear failure handling. Includes runnable Node.js code and responsible-access guidance.
Render HTML in headless Chrome with Go, capture it as an image, then encode it as WebP. Includes runnable code, deployment guidance, and troubleshooting.
When TestNG retries in Eclipse but not on the command line, compare the runner, classpath, suite, listeners and JVM settings to find the configuration drift.
Find why Puppeteer runs callbacks twice, then fix listeners, navigation races, new-document scripts, pages, popups, and request interception.
Trace the deleted WebDriver session, validate IE Mode and IEDriverServer settings, then fix teardown, concurrency, and legacy IE configuration issues.
Learn how to screenshot TikTok on iPhone and Android, save videos or photos, capture scrolling pages, and understand screenshot notifications.
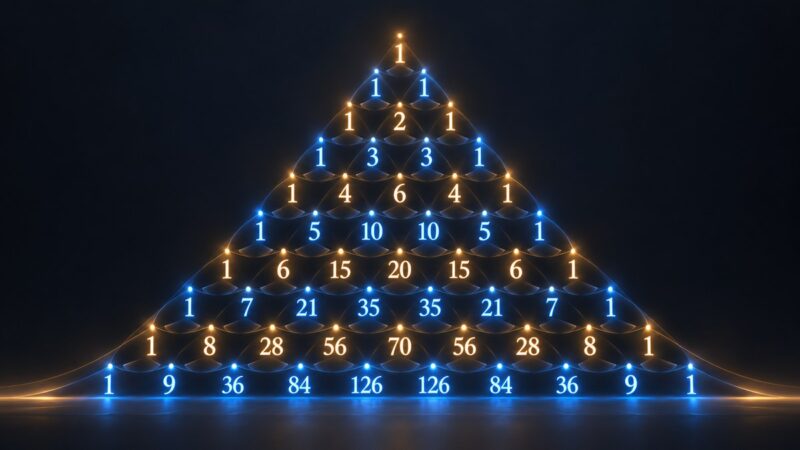
Learn to generate Pascal's Triangle in Python, print rows clearly, center the output, validate input, and choose an efficient implementation.
Control embedded video with provider settings for basic behavior and a player API for custom playback. Learn the YouTube, Vimeo and Wistia options and limits.
Diagnose Selenium screenshot failures by separating browser capture problems from file-writing errors, then fix context, output path, element, and page-scope issues.
Learn Python’s conditional expression syntax, evaluation order, precedence, nesting, practical patterns, pitfalls, and when to use if/else instead.
Learn when a webhook should start a screenshot or deliver its result, then build a secure, reliable capture workflow with runnable examples.
Capture rendered pages from Cloudflare Workers with Browser Run, full-page options, Puppeteer, limits, troubleshooting, and a simpler API alternative.
Yelp prohibits automated scraping except where expressly authorized. Learn the compliant API options, restrictions, and how to capture permitted pages.
Render print-ready paginated previews in Nuxt with Paged.js, avoid SSR errors, and choose the right path for automated PDFs.
Use dedupe_duration_s to reuse identical recent images and save credits. Learn its defaults, limits, matching rules, client support, and reliability edge cases.
A wait can pass while Selenium still cannot interact with an element. Diagnose the locator, required state, overlays, and viewport before changing timeouts.
Fix Selenium element screenshot errors by checking driver support, separating capture from file I/O, and cropping a full-browser screenshot when needed.