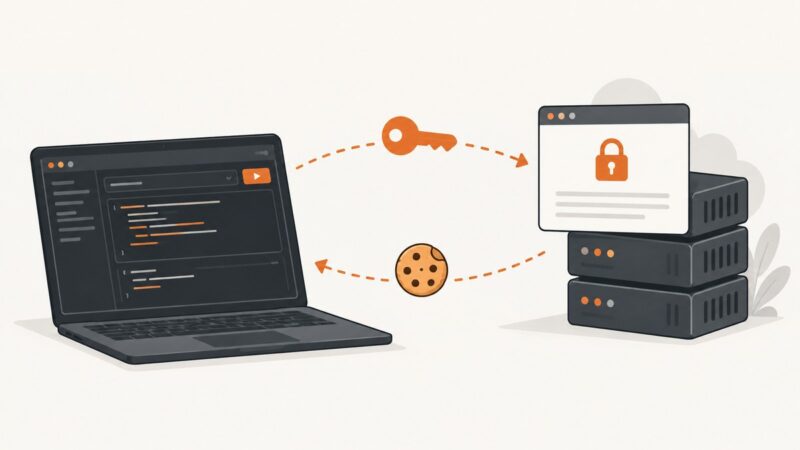
How to Capture Authenticated Web Pages with PHP Guzzle
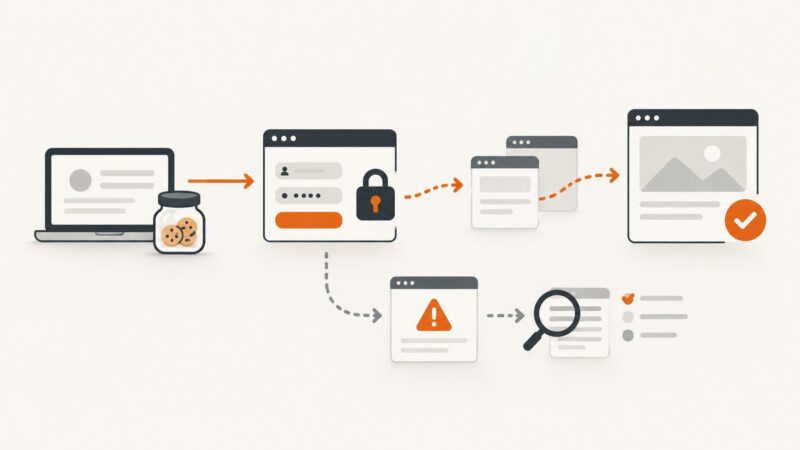
Use one Guzzle client and cookie jar to log in and fetch an authorized page. Learn how to handle redirects, validate the response, and diagnose login failures.
Use one Guzzle client and cookie jar to log in and fetch an authorized page. Learn how to handle redirects, validate the response, and diagnose login failures.
Sign in with Capybara or Selenium, verify the protected page loaded, then capture it safely in Ruby.
Learn how to preserve website screenshots with reliable metadata, Wayback captures, WARC files, redundant storage, and reproducible automation.
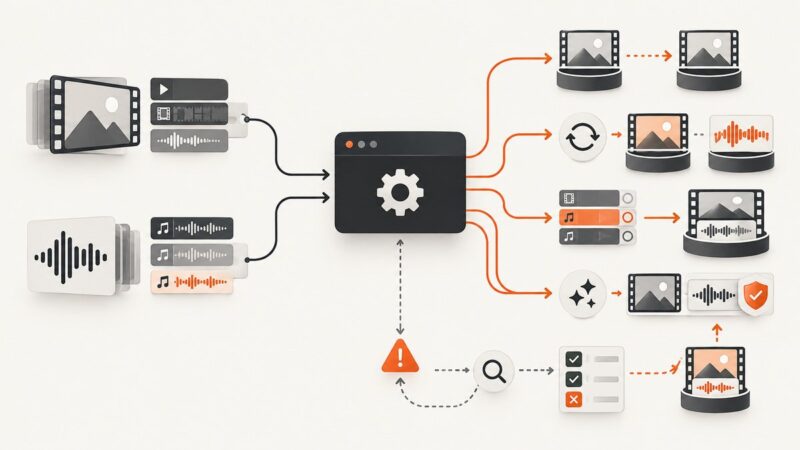
Convert video and audio with FFmpeg: remux without re-encoding, transcode safely, select streams, preserve quality, and troubleshoot common failures.
Cars & Bids prohibits unauthorized scraping. Learn what you can review, how to request permission, and how to build a compliant workflow.
Learn how to retrieve authorized Audible product metadata, parse JSON-LD safely, handle locales and failures, and choose an API workflow.
Set reliable screenshot API timeouts by separating request, navigation, and readiness limits, with examples for major providers and ScreenshotNeo.
Read href, src, class, data-* and other HTML attributes with browser JavaScript, Playwright or Selenium—and learn when you need a live DOM property instead.
Connect Puppeteer to a hosted Chrome session, run a real page workflow, and clean up reliably with provider-specific WebSocket settings.
A practical guide to planning, recording, lighting, sound, camera movement, editing, and finishing videos that look intentional and sound clear.
Use CSS attribute negation or Cheerio’s .not() method to select elements missing an attribute, with examples for empty values, scope, and runtime limits.
Build less flaky browser automation with condition-based waits, stable locators, isolated state, retrying assertions, and evidence-driven debugging.
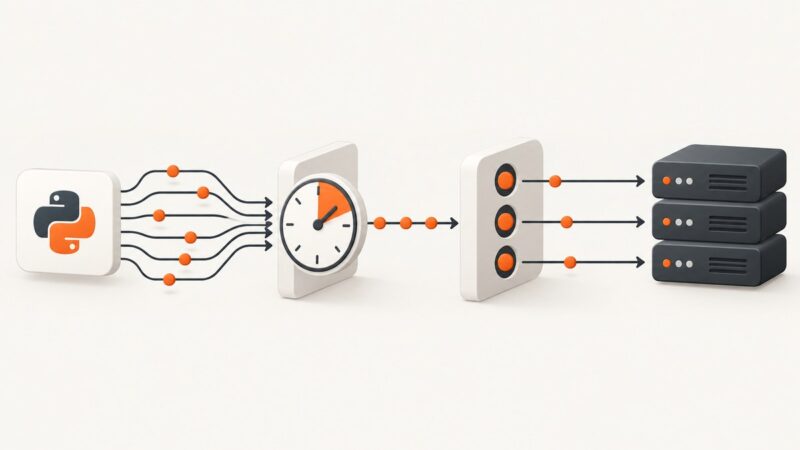
Use separate controls for request rate and concurrency in asyncio, with runnable patterns for aiolimiter, semaphores, retries, and production workloads.
Speed up website screenshots by choosing the right capture scope, readiness checks, image settings, and API architecture.
Learn how to scrape JavaScript-rendered pages with Puppeteer, wait for reliable page states, choose selectors, handle errors, and extract useful data.
Calculate an animated GIF’s total pixel resolution from its canvas, frame count, and per-frame rectangles with ImageMagick commands and scripts.
Generate page-specific Open Graph images in Astro from route or content data, then add their public URLs to each page’s metadata.
Automate website screenshots with Playwright or a hosted API. Learn how to capture the right page state, handle dynamic content, save images, and debug failures.