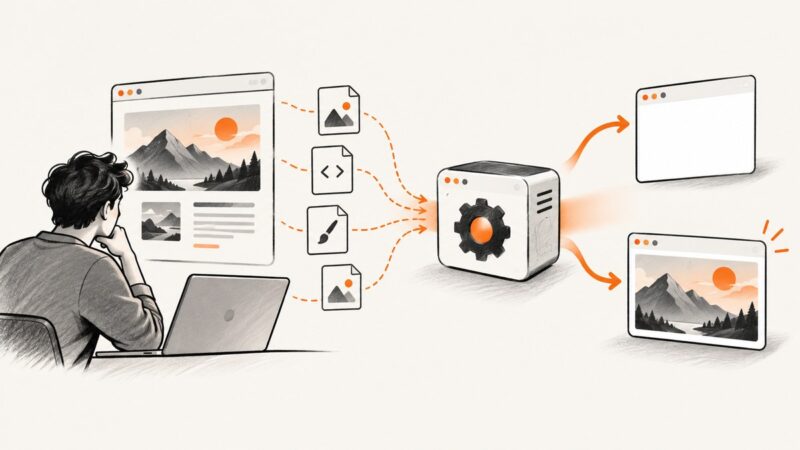
How to Fix wkhtmltopdf Cannot Convert Local File Errors
Fix wkhtmltopdf local-file errors by checking the input, referenced paths, process permissions, and the right access flags.
Fix wkhtmltopdf local-file errors by checking the input, referenced paths, process permissions, and the right access flags.
Fix Puppeteer's libgobject-2.0.so.0 error by finding missing Chrome libraries, installing the right Linux packages, and rebuilding your runtime.
Save PhantomJS renders correctly, expose them through a URL, and display or protect them in PHP with complete code and troubleshooting.
Find the pathname behind IMGKit’s EACCES error, then fix the exact executable, asset, cache, tempfile, or output permission that Rails needs.
A practical diagnostic guide for IMGKit, wkhtmltoimage, ImageKit and CentOS Rails deployments, including dependency checks, fixes and safer alternatives.
wkhtmltopdf documents a global page offset, not a built-in mid-document reset. Learn what it can do and how to handle section-specific numbering safely.
A reliable Playwright workflow for React screenshots: wait for real readiness, freeze motion, stabilize rendering, and diagnose flaky captures.
Set PhantomJS’s resource timeout before navigation, capture timeout metadata, and use a watchdog when the script itself may hang.
PhantomJS renders web pages to images but does not document PDF input. Learn the correct PDF rasterization workflow and safer alternatives.
Convert an HTML string to PDF from Java with wkhtmltopdf, configure the wrapper and renderer, handle common failures, and choose an alternative for screenshots.
Install a prebuilt wkhtmltopdf package with patched Qt for your OS and CPU, then verify headers, footers, and headless rendering without compiling.
Learn why wkhtmltopdf uses print CSS, how to restore screen styles, and how to diagnose missing rules, assets, and version-specific behavior.
Install wkhtmltopdf safely on Alpine with Python 3.6 by matching Alpine, architecture, Qt features, libraries, and fonts.
Wait for the page state your scraper needs, then extract its rendered HTML with Puppeteer’s page.content() or the live DOM.
Diagnose wkhtmltoimage freezes by separating readiness waits, failed resources, and version-specific bugs with a reproducible workflow.
Diagnose Capybara and Poltergeist hangs by tracing whether the wait belongs to test synchronization, page resources, or PhantomJS communication.
Fix wrong fonts, missing Unicode glyphs, and blurry text in wkhtmltoimage by checking the Qt build, fontconfig, font files, access, and fallback behavior.
Diagnose blank IMGKit output and missing embedded images with practical checks for wkhtmltoimage, paths, Xvfb, and HTML resources.