How to Take a Full-Page Screenshot in Chrome with Selenium
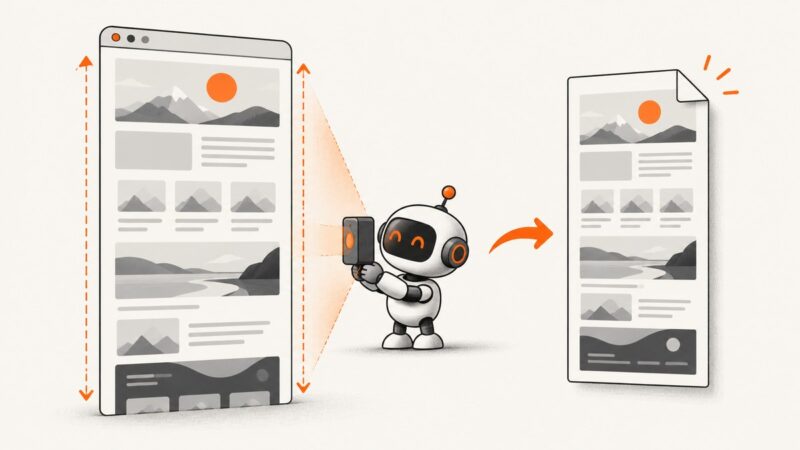
Capture a full-page Chrome screenshot with Selenium using CDP, decode the PNG, and handle version, loading, and troubleshooting details.
Capture a full-page Chrome screenshot with Selenium using CDP, decode the PNG, and handle version, loading, and troubleshooting details.
Learn how to extract href values, resolve relative URLs, filter internal links, remove duplicates, and crawl JavaScript-rendered pages safely.
Build a PDF endpoint in Remix with a Resource Route, Puppeteer, reliable page readiness, correct response headers, and a link that opens the PDF.
Learn safe, bounded retries in Ruby with Net::HTTP and Faraday, including idempotency, backoff, Retry-After, errors, testing, and production guidance.
Build a reliable Go crawler for infinite scroll pages with chromedp, explicit progress checks, bounded retries, and production troubleshooting.
Use Selenium and Chrome DevTools to save a rendered page, its CSS, images, iframes, and shadow DOM as one offline MHTML file.
Generate PDFs directly with Playwright’s page.pdf() API, control print CSS, wait for dynamic content, and avoid the browser print dialog entirely.
Switch into an iframe, locate the element you need, and capture it directly with Selenium WebDriver. Includes nested frames, cropping, and troubleshooting.
Set solid, transparent, full-page, element, PDF, and test screenshot backgrounds in Playwright with practical code and troubleshooting.
Build Slack link previews with Open Graph metadata or a custom app, then generate clean preview images with ScreenshotNeo.
Learn how to locate fields, enter text with Selenium or Playwright, submit reliably, debug failures, and capture clean results with ScreenshotNeo.
Capture an X post on iPhone, Android, or desktop, including long posts and attached photos. Learn how to crop, save, and check a screenshot before sharing.
Guzzle sends outbound requests; PHP receives webhooks. Read JSON safely from php://input, validate the sender, and use Guzzle only for follow-up calls.
Puppeteer is JavaScript, and its Python port is unmaintained. Learn the policy limits, a runnable authorized browser example, and safer options for merchant-owned product data.
Use Etsy Open API v3 to collect authorized listing, price, and shop data while avoiding prohibited screen scraping.
Fix Requests’ MissingSchema error by finding the URL or proxy value without a scheme, validating it, and resolving relative links correctly.
Use Playwright’s download event for attachments, handle PDF viewer navigation separately, and avoid confusing source downloads with page printing.
Install Puppeteer Stealth, extract pages reliably, troubleshoot detection and failures, and compare local scraping with a managed screenshot API.