How to Scrape Prices From Websites With Python
Build a Python price monitor with requests and Beautiful Soup, handle JavaScript-rendered prices, normalize currencies, and store auditable history.
Build a Python price monitor with requests and Beautiful Soup, handle JavaScript-rendered prices, normalize currencies, and store auditable history.
Learn how to tell whether a panel is hidden, off-canvas, or modal by inspecting its markup, styles, accessibility state, and behavior.
Use XPath 1.0 predicates or path unions to match several element names. Learn which form fits your XPath version, namespaces and runtime.
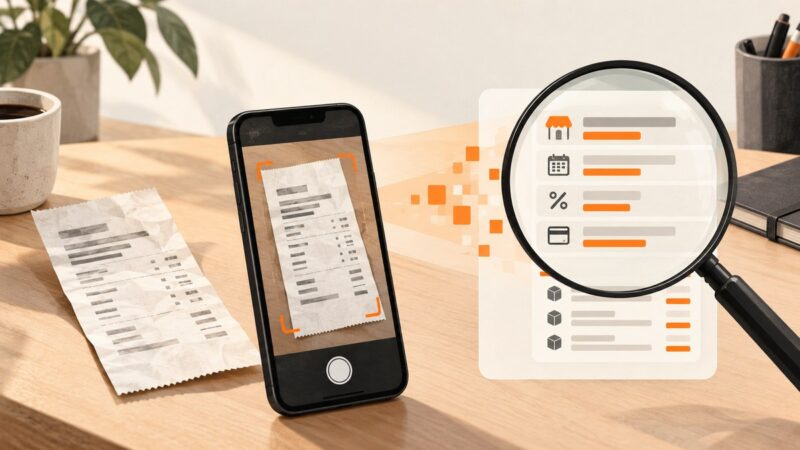
Learn how to turn receipt photos and scans into accurate, reviewable expense data, including fields, OCR limits, recordkeeping, and workflows.
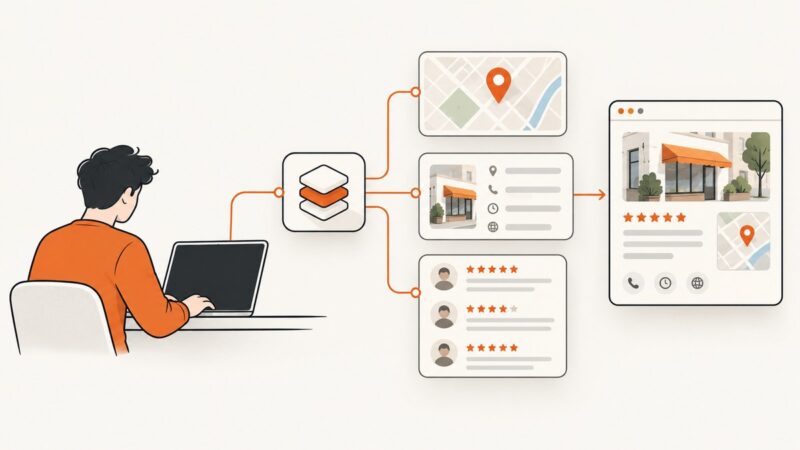
Use Places API (New) to request selected place details and reviews. Learn the compliant workflow, runnable code, display rules, limits, and troubleshooting steps.
Set Playwright’s snapshot path template to keep visual regression references under one shared folder while preserving test and project organization.
Headed and headless Playwright runs can use different Chromium implementations, environments, and capture times. Here’s how to compare them and make DOM snapshots reproducible.
Fix Playwright waitForEvent timeouts by registering listeners before actions, checking event scope and predicates, and separating events from readiness.
Learn how to fetch, save, request, send, inspect, and troubleshoot XML with cURL, including runnable commands and Python and Node.js examples.
Fix Playwright screenshots that show logged-out pages by saving the right auth state, restoring sessionStorage, and waiting for protected content.
Learn the authorized ways to get Walmart product information, what the documented APIs support, and why public-page scraping requires written permission.
Use Yandex Search API with Python or Node.js, decode XML or HTML responses, handle pagination, authentication, limits, and errors.
Learn to filter selected keys at every level of a nested Python dictionary, with explicit policies for parent branches, mappings, lists, mutation, and cycles.
Build an OCaml scraper with Cohttp and Lambda Soup, choose the right runtime, handle failures, and know when browser rendering is required.
Learn when to set cookies, isolate sessions with BrowserContexts, or configure Puppeteer’s user data directory—with runnable code and troubleshooting.
Set Playwright's locale to change navigator.language, Accept-Language, and regional formatting in one browser context or test.
A closed-page screenshot error means Playwright lost access to the page or its browser state. Find which object closed, trace cleanup, and isolate crashes, site behavior, and connection mode.
Build a reliable price-monitoring workflow: collect product prices with context, respect crawler rules, validate changes, and choose between a custom scraper and a service.