How to Create Thumbnails for Web Apps
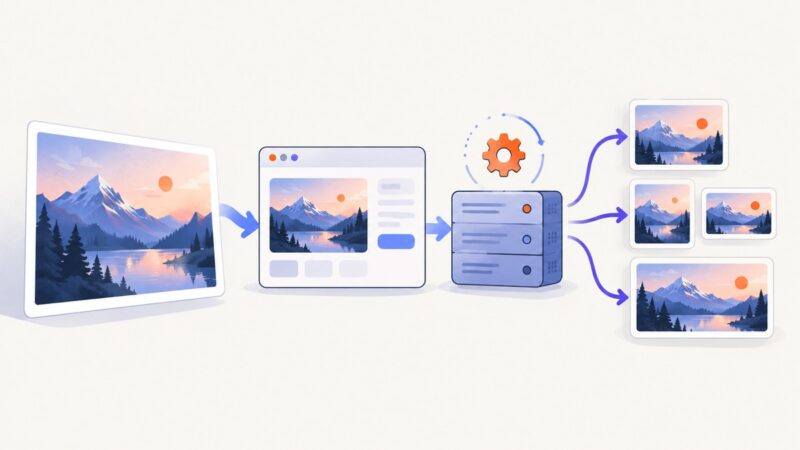
Learn how to generate fast, sharp web app thumbnails with responsive images, Sharp, canvas, ImageMagick, and on-demand services.
Learn how to generate fast, sharp web app thumbnails with responsive images, Sharp, canvas, ImageMagick, and on-demand services.
Build a reliable pipeline that extracts permitted web data, normalizes it into rows, and appends it to Google Sheets with Python, Node.js, cURL, or Apps Script.
Install Node.js correctly on Windows, macOS, or Linux: choose LTS, match your architecture, verify npm, and use a version manager when needed.
Save one page with your browser or mirror an entire site with HTTrack, then test the local copy before you go offline.
Parse Cookie request headers safely in Python, Node.js, and cURL. Learn when to decode values, preserve duplicates, and distinguish Cookie from Set-Cookie.
Capture a full Safari webpage on iPhone, understand Mac’s built-in screenshot options, and choose the right way to save or automate a page capture.
Learn how to capture viewport, full-page, and element screenshots with Playwright headless mode, tune output, fix failures, and automate reliable images.
Use a cookie jar for HTTP scraping and an isolated browser context for JavaScript-driven pages. Learn how to preserve session state without leaking credentials.
G2’s terms require express written consent for automated review collection. Learn how to request access, scope a compliant project, and analyze authorized data.
Learn what causes Python Requests ReadTimeout errors, how to set connect and read timeouts, retry safely, and diagnose slow networks and servers.
Learn why Microsoft Teams link preview images are missing or stale, how to diagnose the cause, and how site owners can fix metadata and image access.
Learn the download attribute, cross-origin rules, Content-Disposition headers, filenames, accessibility, troubleshooting, and reliable PDF download patterns.
Load a remote JavaScript file into a Ruby PDF renderer, resolve its URL, and wait until its work is complete before generating the PDF.
Build a practical Scrapy crawler in Python: install it, extract data with CSS and XPath, export results, debug failures, and crawl responsibly.
Learn when OpenHTMLtoPDF, Flying Saucer, a browser renderer, or ScreenshotNeo is the right way to turn a URL into a reliable PDF from Java.
Build a reliable listings pipeline with APIs or permitted pages, careful extraction, validation, deduplication, and freshness checks.
Convert a raw HTML string to a reliable PDF in Java with iText or OpenHTMLtoPDF, including assets, fonts, page breaks, errors, and production tips.
Learn Playwright’s load states, condition-based waits, timeout diagnosis, and reliable fixes for navigation and assertion failures.