Why Puppeteer PDF Page Size Settings Do Not Work and How to Fix Them
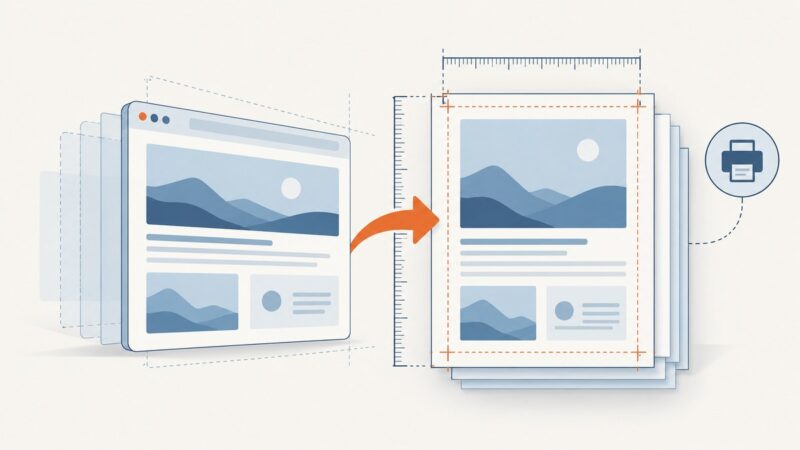
Puppeteer PDF dimensions look wrong when format, width, height, CSS @page, margins, and print media rules conflict. Fix precedence step by step.
Puppeteer PDF dimensions look wrong when format, width, height, CSS @page, margins, and print media rules conflict. Fix precedence step by step.
Remove unwanted white space from Puppeteer PDFs by checking PDF margins, CSS @page rules, print styles, and background settings.
Generate a multi-page PDF with Puppeteer using Page.pdf(), print CSS, paper settings, and reliable page-break rules.
Use Puppeteer to render HTML and create a PDF, while Socket.IO submits jobs and reports progress. Includes runnable Node.js code, PDF options, and troubleshooting.
Make Puppeteer PDFs wait for canvas drawing to finish. Use an application readiness signal, handle fonts and CORS, and choose when to export the canvas as an image.
Load Roboto correctly, wait for font readiness, apply print CSS, and troubleshoot missing or unembedded fonts in Puppeteer PDFs.
Fix reversed Hebrew, English, and numbers in PDFs by correcting source direction, mixed text runs, export settings, and viewer-specific issues.
Missing glyphs in a Puppeteer PDF usually point to font coverage or fallback inside the container. Diagnose the exact script, install suitable fonts, and check print CSS and font loading.
Merge Puppeteer PDF buffers in memory with pdf-lib, preserve page order, handle errors, and return one PDF without temporary files.
Make a webpage fit A4 PDF pages with print CSS, reliable browser settings, and fixes for clipping, tiny text, blank pages, and missing fonts.
Use a semantic <thead> and print CSS to repeat table headings in Puppeteer PDFs. Get runnable code, pagination options, and fixes for common Chromium layout problems.
Learn why HTML page breaks create blank PDF pages and how to fix pagination in CSS, Puppeteer, and WeasyPrint.
Save any HTML page or local document as a PDF in Chrome on desktop or Android, with print settings, troubleshooting, automation, and an API option.
HTML normally becomes multiple PDF pages automatically. Fix clipping with print CSS, controlled page breaks, and a reliable rendering pipeline.
Fix missing S3 images in Puppeteer PDFs with presigned URLs, explicit image readiness checks, and reliable troubleshooting.
A broken Base64 image in a Puppeteer PDF header can come from the data URI, template, PDF options, or browser version. Use this diagnostic sequence to isolate it.
Learn when to convert a full-page screenshot to PDF, when to print a webpage, and how to create reliable PDFs on desktop, iPhone, Android, Python, and Node.js.
Fix Puppeteer PDFs that print before client-side rendering finishes. Add an app-owned readiness signal, wait for it with a timeout, then call page.pdf().