How to Load CSS from a String When Converting HTML to PDF in Ruby
Pass inline CSS safely to Ruby HTML-to-PDF tools. Learn the Grover option, PDFKit and Wicked PDF fallbacks, path fixes, debugging, and production tips.
Pass inline CSS safely to Ruby HTML-to-PDF tools. Learn the Grover option, PDFKit and Wicked PDF fallbacks, path fixes, debugging, and production tips.
Fix Puppeteer’s null textContent error by checking selectors, timing, frames, optional fields, and placeholder nodes with reliable code patterns.
Enable Puppeteer to test XMLHttpRequest reads from local files with Chromium’s file-access flag, understand its security limits, and troubleshoot failures.
Learn how to collect Reddit data with Python using OAuth, pagination, rate-limit handling, deletion workflows, and compliant storage.
Learn how to collect Zoro product data responsibly: check authorization first, request an approved route, and build a timestamped, validated export.
Grant camera permission to Puppeteer’s browser context before navigation, then wait for a deterministic stream-ready signal instead of the permission prompt.
Fix Selenium URL errors after a tab switch by waiting for the new handle, switching explicitly, and checking the destination page state.
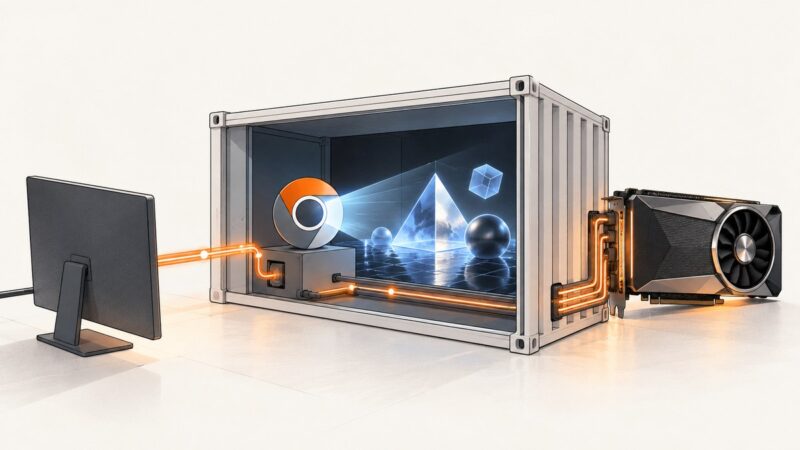
Expose an NVIDIA GPU to Docker, configure headless Chrome for WebGL, and verify that rendering uses the GPU instead of assuming device access is enough.
Use Playwright’s full-page screenshot option to capture a page’s entire scrollable content, save it to a file, or process the resulting bytes.
Learn how to replace a featured image, change WordPress thumbnail dimensions and crops, regenerate old image sizes, and troubleshoot theme-specific results.
Set a reliable Chrome viewport in Rails system tests with Selenium, verify it in CI, and avoid common headless sizing problems.
Learn how HTML becomes an editable DOCX, with Pandoc commands, Python and Node.js examples, styling, assets, troubleshooting and fidelity limits.
A Puppeteer element wait times out when its selector never reaches the requested state. Diagnose the page, selector, visibility, frame, navigation, and timeout in order.
Capture website screenshots with Selenium in Python, save PNGs or bytes, target elements, and handle full-page limits, setup issues, and failures.
Find out why headless browser automation fails by making the session observable, saving replayable evidence, and separating timing, code, browser, and CI problems.
Scroll lazy-loaded images into view with Puppeteer, wait for a real URL, and extract currentSrc, src, data attributes, and srcset reliably.
Stealth proxies do not create permission to collect ZoomInfo data. Learn the authorization checks, safer export paths, and an auditable workflow.
Convert HTML to PNG, JPEG, WebP, or PDF with html2canvas, Playwright, Puppeteer, or ScreenshotNeo. Includes runnable code and troubleshooting.