How to Scroll a Web Page Before Capturing a Screenshot
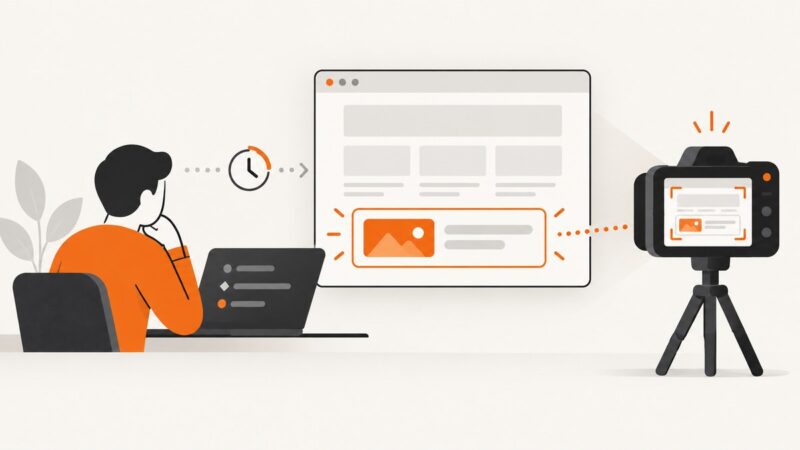
Learn when to scroll manually and when to capture a full page, viewport, or element with Playwright or Puppeteer. Includes runnable code and fixes for tricky pages.
Learn when to scroll manually and when to capture a full page, viewport, or element with Playwright or Puppeteer. Includes runnable code and fixes for tricky pages.
Inject a remote stylesheet reliably with Playwright or Puppeteer, wait for it to load, troubleshoot timing issues, and automate clean captures.
Connect webhook events to browser automation reliably. Learn the trigger patterns, runnable examples, security, retries, and ways to handle long-running browser tasks.
Link every screenshot to an account or pseudonymous ID in your app while keeping attribution, analytics, and privacy boundaries clear.
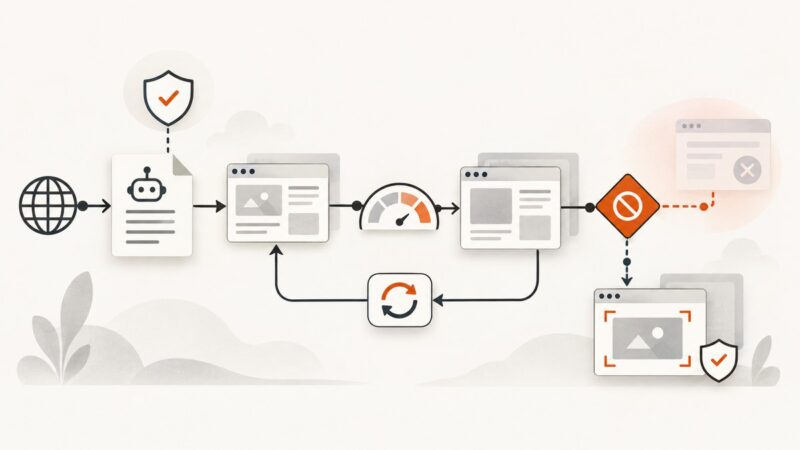
Learn a reliable, permission-first scraping workflow: robots.txt, rate limits, retries, refusal handling, and safer screenshot automation.
Use BRAIN’s partner API for authorized product data. When you need public page fields, extract Product JSON-LD first and render JavaScript when required.
There is no reliable block-proof Instagram scraper. Learn the authorized API route, enforcement limits, compliant workflows, and safer screenshot options.
Learn what Cloudflare 1006, 1020 and 1015 mean, how to unblock access safely, and what to send the site owner.
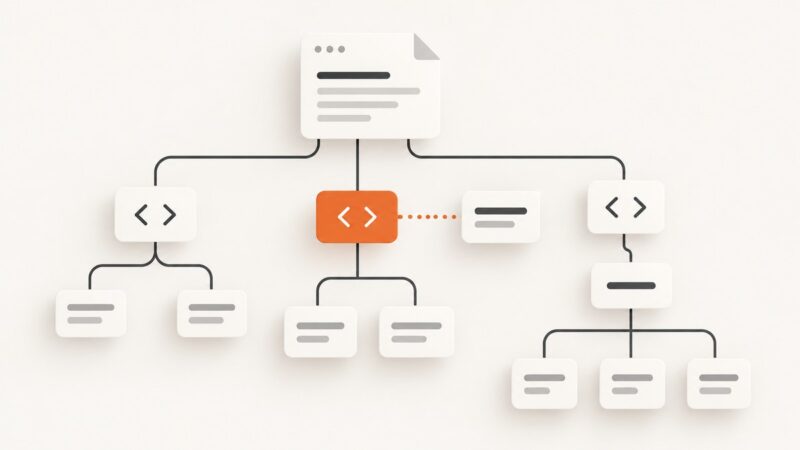
Use BeautifulSoup’s sibling methods for values beside a label, or document-order traversal when the target is elsewhere. Includes runnable examples and fixes for common parsing surprises.
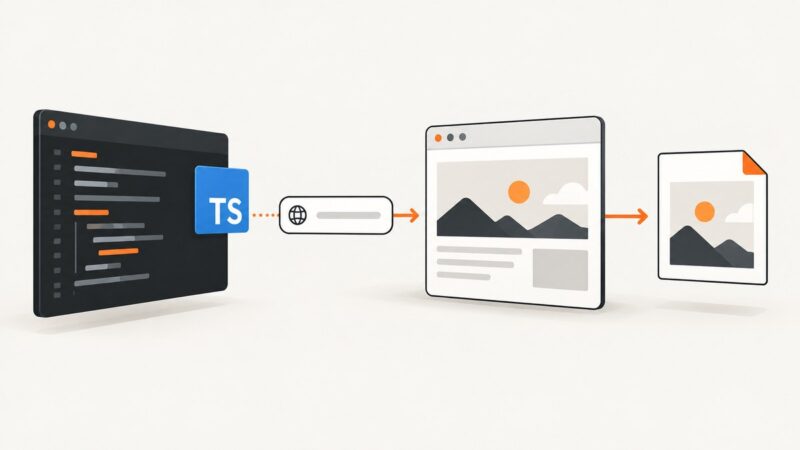
Use Playwright in TypeScript to capture webpages as JPEG, control quality and scale, save files or buffers, and handle full-page and element screenshots.
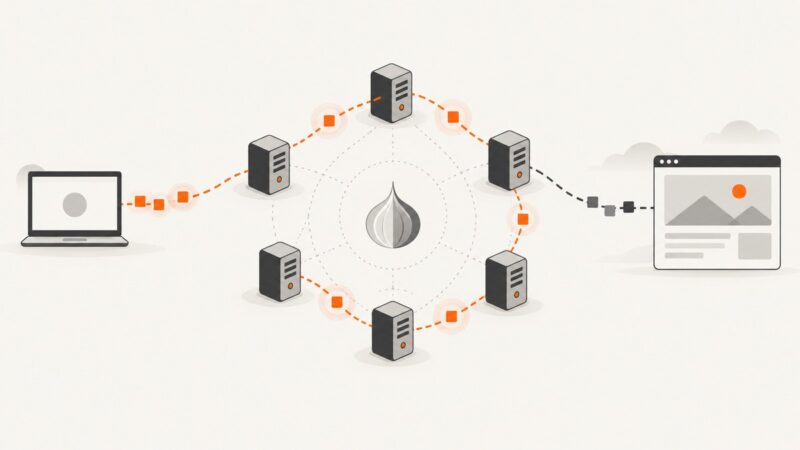
Configure Tor SOCKS5 for Python and browser scraping, prevent DNS leaks, and understand Tor’s limits, safe request rates, and alternatives.
Configure Playwright or Selenium sessions with the right browser, profile state, proxy, credentials and timeouts. Includes runnable examples and fixes for common failures.
Learn how to fetch HTML, parse it with Beautiful Soup, extract text, links and structured fields, and handle JavaScript, malformed markup and crawl limits.
Use Beautiful Soup sibling navigation to find the next or previous HTML node, skip whitespace, and select matching tags reliably.
Configure HTTP, HTTPS, and SOCKS proxies in Playwright and Puppeteer, authenticate safely, route browser installs, and troubleshoot common failures.
Run Selenium WebDriver tests remotely with a local Grid, then scale to multiple nodes or managed browsers when your matrix needs it.
Edit HTML and CSS safely in DevTools, preserve changes with Chrome Local Overrides, and capture clean, repeatable screenshots.
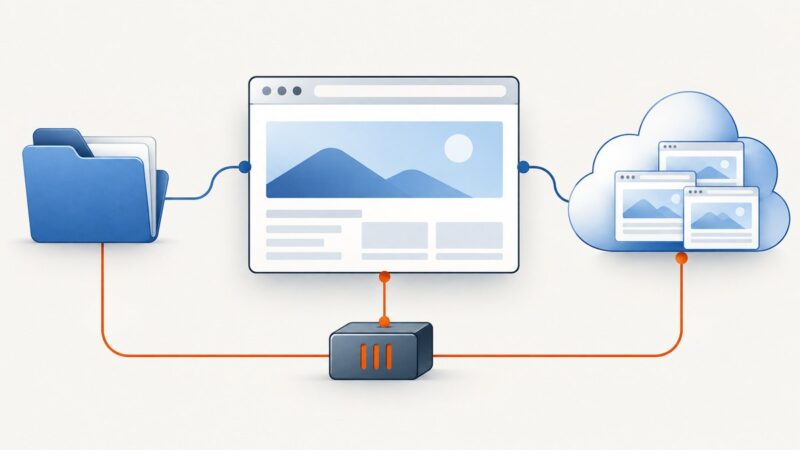
Configure browser, HTTP, and session caching in Playwright, Puppeteer, and Selenium, with CI guidance, troubleshooting, and a managed screenshot option.