How to Fix wkhtmltopdf PDFs That Shrink When Text Is Too Long
Find out whether smart shrinking, page width, long unbroken text, or pagination is making your wkhtmltopdf output too small—and how to diagnose it safely.
Find out whether smart shrinking, page width, long unbroken text, or pagination is making your wkhtmltopdf output too small—and how to diagnose it safely.
Learn why align-items may fail in wkhtmltopdf, how flex axes and container space work, and which fallbacks make PDF layouts reliable.
Images work in Rails but vanish from wicked_pdf PDFs? Trace renderer paths, assets, permissions, and wkhtmltopdf settings with this practical guide.
Diagnose slow Rotativa PDFs in production by measuring the full pipeline, checking resource loading, and tuning wkhtmltopdf settings safely.
Learn what wkhtmltopdf can authenticate, how to diagnose IIS Windows Authentication, and which workarounds fit HTTP, integrated, and session-based access.
Fix missing CSS, images, and fonts in Django PDFs by checking collection, rendered asset URLs, renderer access, and local-file settings.
Fix Wicked PDF errors caused by missing binaries, PATH, permissions, Alpine, OpenSSL, fonts, temporary files, and broken asset URLs.
Convert HTML files to PDF in C# with wkhtmltopdf, local assets, layout options, troubleshooting, and a ScreenshotNeo alternative.
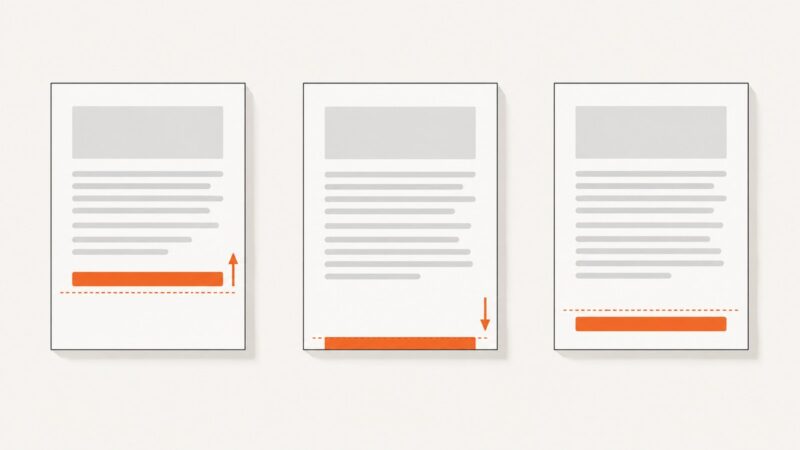
Fix high, clipped, or overlapping wkhtmltopdf footers by checking the build, page margins, footer spacing, and HTML layout in a controlled sequence.
Enable background printing in your PDF renderer, then define the image in print CSS or a page rule. Here are runnable examples and fixes for Puppeteer, Playwright, and WeasyPrint.
Fix missing SVGs in WickedPDF PDFs by checking asset URLs, local-file permissions, renderer limits, and reliable fallbacks.
Inject JavaScript into in-memory HTML with Playwright, wait for rendering, and create a reliable PDF in Python.
Diagnose page-edge, table, and pagination borders in wkhtmltopdf with reproducible tests, CSS checks, workarounds, and renderer alternatives.
Diagnose PDF page-load errors with navigation checks, resource logs, readiness waits, print settings, and reliable Playwright fixes.
Convert an HTML string to PDF bytes in C# with wkhtmltopdf and DinkToPdf, configure rendering and deployment, and troubleshoot common failures.
Add reliable page breaks to KnpSnappy PDFs with CSS, fix ignored rules, keep content together, and troubleshoot wkhtmltopdf layouts.
Fix missing or garbled Unicode in Wicked PDF by checking HTML encoding, fonts, wkhtmltopdf settings, and header/footer rendering.
Set a deliberate PDF page height with print CSS, Puppeteer, or Playwright. Learn how dimensions, margins, and CSS/API precedence affect exports.